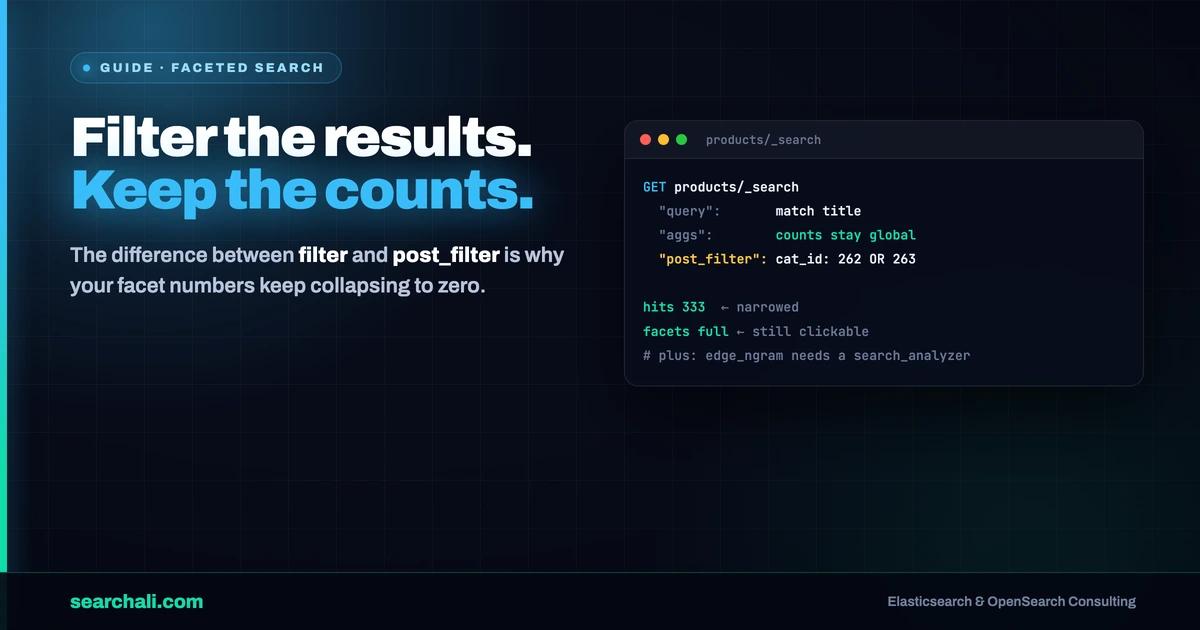
A user ticks two category checkboxes in your store. The product list narrows—good. Then every other facet in the sidebar collapses to only the options that survive the filter, and the user can no longer see what else exists. That is the classic faceted-search bug, and it comes from putting the filter in the wrong place.
I hit exactly this while building search for a US medical-supplies e-commerce platform (anonymized; the work came through their agency). Product catalog in Postgres, synced to Elasticsearch via Logstash, a Laravel storefront in front. The fix is a pattern every e-commerce search needs: post_filter plus cross-filtered aggregations. Here it is, with the real queries.
Quick answer: A filter inside query runs before aggregations, so facet counts shrink with every click. post_filter runs after aggregations and only narrows the hit list, so your facets keep global counts. For multi-facet UX, add one filter sub-aggregation per facet that applies the other facets' selections. Same request, three placements, three different jobs.
Why filter placement decides your facet counts
One search request does two jobs at once: return hits, and compute the sidebar. Elasticsearch gives you three places to put a filter, and each changes what the user sees:
- Inside
query— affects both hits and aggregations. Use for constraints that should always apply (e.g.is_active: true). - Inside an aggregation (
filteragg) — affects only that aggregation. Use to cross-filter one facet by the selections made in other facets. - In
post_filter— affects only the hit list, after aggregations run. Use for the user's own facet selections.
Elastic's own docs describe post_filter for exactly this use case—see filter search results in the Elasticsearch reference.
The pattern: global aggs, cross-filtered aggs, post_filter
This is the shape we shipped (index and field names generalized, structure verbatim from the working request). The user has selected seven category checkboxes:
GET products/_search
{
  "query": {
    "bool": {
      "should": [
        { "match": { "title": { "query": "oximeter", "minimum_should_match": "75%" } } },
        { "match": { "title.standard": { "query": "oximeter", "fuzziness": "AUTO", "minimum_should_match": "100%" } } },
        { "match_phrase": { "title.standard": { "query": "oximeter" } } }
      ]
    }
  },
  "size": 12,
  "aggs": {
    "categories": {
      "terms": { "field": "categories.cat_label.keyword", "size": 1000 },
      "aggs": {
        "cat_id": { "terms": { "field": "categories.cat_id", "size": 1000 } }
      }
    },
    "manufacturers": {
      "terms": { "field": "manufacturer.keyword", "size": 1000 }
    },
    "manufacturers_filtered": {
      "filter": {
        "bool": {
          "should": [
            { "term": { "categories.cat_id": "262" } },
            { "term": { "categories.cat_id": "263" } }
          ]
        }
      },
      "aggs": {
        "manufacturers": { "terms": { "field": "manufacturer.keyword", "size": 1000 } }
      }
    }
  },
  "post_filter": {
    "bool": {
      "must": {
        "bool": {
          "should": [
            { "term": { "categories.cat_id": "262" } },
            { "term": { "categories.cat_id": "263" } }
          ]
        }
      }
    }
  }
}
Three things to read out of this:
The user's selections live in post_filter
The seven selected cat_id values sit in post_filter as term clauses under a should (categories OR each other). Hits narrow; aggregations do not. The category facet keeps showing all categories with their full counts, so unchecking and exploring stays possible.
Each facet gets a cross-filtered twin
manufacturers is global. manufacturers_filtered wraps the same terms agg in a filter agg carrying the category selections. The UI shows manufacturer counts that respect the chosen categories—without hiding the category facet's own breadth. Rule of thumb: a facet is filtered by every selection except its own.
Sorting still works on the filtered list
post_filter composes cleanly with sort. When the user switched to "Price low to high" the same request simply carried "sort": [{ "pp_unit_price": { "order": "asc" } }] alongside the post_filter. With seven filters applied the storefront showed 333 results, paged 12 at a time.
Field notes from a health e-commerce build
The catalog documents carry title, item_description, manufacturer, and a categories array with cat_id, cat_label, and cat_full_name (a >-separated hierarchy path). Every string field was mapped through a dynamic_templates rule: text with an autocomplete analyzer plus a .keyword subfield for facets. The autocomplete analyzer: standard tokenizer, lowercase, kstem, and an edge_ngram filter from 1 to 20 characters.
The header autocomplete used _msearch: one query for products on title with highlighting, one terms aggregation on manufacturer.keyword ordered by average score with top_hits—so the dropdown shows "items found" and "manufacturers found" from a single round trip.
The edge_ngram trap: 1542 results that should be 0
During testing, a nonsense term returned 1,542 results. The cause: the edge_ngram analyzer (with min_gram: 1) was applied at search time too, because no search_analyzer was set. The query itself got shredded into 1–20 character grams, and single-letter grams match almost the whole catalog—fuzziness: AUTO made it worse. The fix is standard: keep edge_ngram as the index-time analyzer and set "search_analyzer": "standard" on autocomplete fields. If you use partial matching, this is the first thing to check.
One more field note: during development, Elasticsearch CORS settings (http.cors.enabled, allow-origin) were opened to let the browser query the cluster directly. Fine for a prototype—do not ship it. Route production traffic through your backend or a search proxy so credentials and the cluster surface stay private.
No conversion, latency, or revenue numbers appear here because they are not in the source pack—the observable outcomes were the corrected match behavior, stable facet counts under seven simultaneous filters (333 results), and price sorting on the filtered list. If you want visibility into what your queries actually do in production, that is exactly what searchali.com/en/monitoring is for.
Key Takeaways
- User facet selections go in
post_filter, never inquery—otherwise your sidebar collapses on every click. - Give each facet a
filter-agg twin carrying the other facets' selections. Facet counts then respect context without losing breadth. - Set
search_analyzerwhenever you useedge_ngram. Index-time grams + query-time grams = matches for garbage input. min_gram: 1is aggressive. Start at 2–3 unless single-character prefixes are a hard requirement.- Sort composes with
post_filter. Price sorting on a filtered list needs no query restructuring. - CORS-open clusters are a dev shortcut, not an architecture. Put a backend in front before launch.
Frequently Asked Questions
Does post_filter make queries slower?
It can, slightly: hits matching the query but excluded by the post_filter are still scored, and aggregations run over the pre-filter set—that is the point. In this build the always-on constraints stayed in query, and only facet selections went to post_filter, which keeps the cost contained.
Why not run two queries instead—one for hits, one for facets?
You can, via _msearch (this project used it for autocomplete). But one request with post_filter plus filtered aggs keeps hits and facets consistent from the same shard snapshot and halves the round trips on every filter click.
How do I filter one facet by the others without hiding its own options?
Per facet, build a filter aggregation containing every other facet's selections, with the facet's terms agg nested inside. The category facet is filtered by manufacturer selections and vice versa—each stays browsable within the user's current context.
Should facet fields be keyword or text?
Facets aggregate on exact values, so use keyword (here: manufacturer.keyword, categories.cat_label.keyword). The multi-field pattern—text for matching plus a .keyword subfield for aggregations and sorting—covers both jobs from one source field.
Building faceted search on Elasticsearch or OpenSearch? I have shipped this pattern in production. → searchali.com