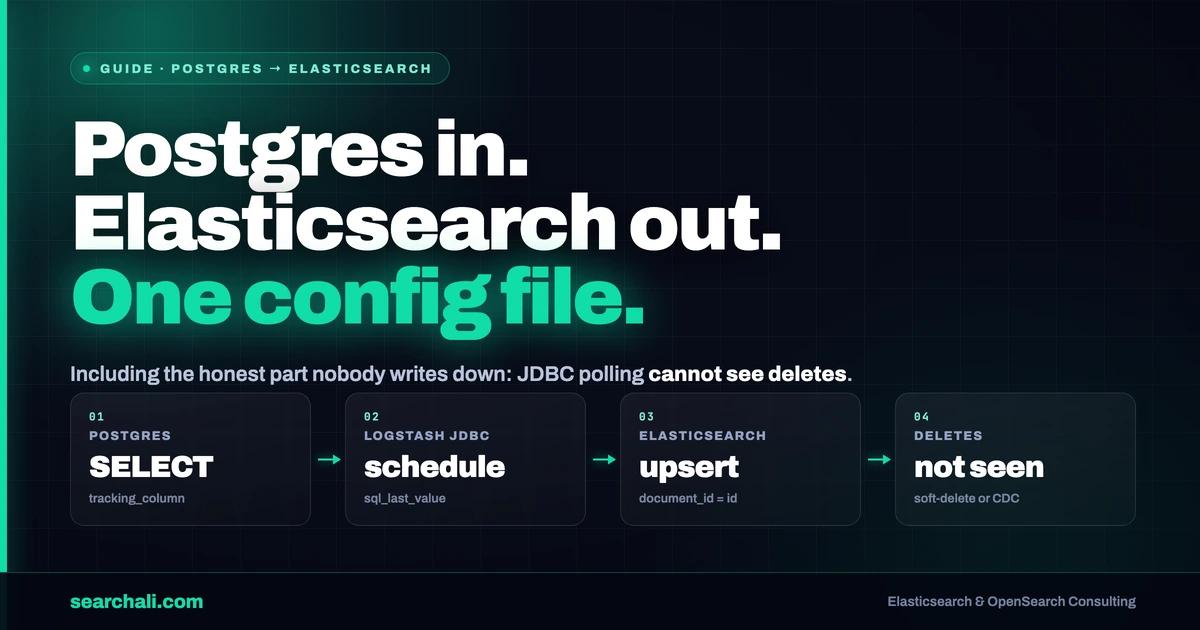
You have relational data in PostgreSQL and you want it searchable in Elasticsearch—full-text queries, aggregations, Kibana dashboards. You do not need Kafka, Debezium, or a custom ETL service to get started. Logstash ships a JDBC input that turns a SQL statement into a scheduled sync pipeline.
This guide is built from a working lab I use to demonstrate exactly this flow: PostgreSQL in Docker (loaded with the classic world sample database), a secured 3-node Elasticsearch cluster with Kibana from Elastic's official Docker Compose, and Logstash 8.4.0 pulling rows over JDBC every minute. Every config below is the real thing, with credentials replaced by placeholders.
Quick answer: Drop the PostgreSQL JDBC driver jar into Logstash, point a jdbc input at your database with a SQL statement and a cron schedule, and send the rows to an elasticsearch output with document_id => "%{id}" so re-runs update documents instead of duplicating them. For incremental sync on append-only tables, use WHERE id > :sql_last_value with tracking_column. One honest caveat: the JDBC input cannot see deletes—plan for that separately.
The architecture
Three moving parts, each in its own container or process:
- PostgreSQL — a Docker image with the sample data baked in via
docker-entrypoint-initdb.d. - Elasticsearch + Kibana — Elastic's get-started
docker-compose.yml: a setup container generates a CA and per-node TLS certificates, three ES nodes come up with security enabled, Kibana lands on port 5601. - Logstash — runs the JDBC input on a schedule and bulk-indexes the results.
The Postgres side is a four-line Dockerfile:
FROM postgres
ENV POSTGRES_PASSWORD <your-password>
ENV POSTGRES_DB world
COPY world.sql /docker-entrypoint-initdb.d/
docker build -t my-postgres-db ./
docker run -d --name my-postgresdb-container -p 5432:5432 my-postgres-db

# sanity checks
docker exec -it my-postgresdb-container psql -U postgres -d world -c "\dt"
docker exec -it my-postgresdb-container psql -U postgres -d world -c "SELECT * FROM country"
For Elasticsearch and Kibana, use Elastic's official Docker Compose guide—docker-compose up -d and you get TLS and authentication out of the box. Since the cluster speaks HTTPS, copy the generated CA out of the container so your clients can verify it:
docker cp <es-container>:/usr/share/elasticsearch/config/certs/ca/ca.crt /tmp/ca.crt
curl -u elastic:<your-password> https://localhost:9200 --cacert /tmp/ca.crt
Setting up the Logstash JDBC input
Logstash does not bundle database drivers. Download the PostgreSQL JDBC jar and make it visible to Logstash. In recent versions the simplest reliable path is dropping it into the internal jars directory (you can also use jdbc_driver_library):
wget https://artifacts.elastic.co/downloads/logstash/logstash-8.4.0-darwin-x86_64.tar.gz
tar -xvf logstash-8.4.0-darwin-x86_64.tar.gz
cp postgresql-42.3.3.jar logstash-8.4.0/logstash-core/lib/jars/postgresql-jdbc.jar
./logstash-8.4.0/bin/logstash -f logstash.conf
Here is the complete, working pipeline, sanitized:
input {
    jdbc {
        jdbc_connection_string => "jdbc:postgresql://localhost:5432/world"
        jdbc_user => "postgres"
        jdbc_password => "<your-password>"
        jdbc_driver_class => "org.postgresql.Driver"
        statement => "SELECT * FROM country"
        schedule => "* * * * *"
    }
}

filter { }

output {
    stdout { }
    elasticsearch {
        ssl => true
        hosts => ["https://localhost:9200"]
        index => "country"
        user => "elastic"
        password => "<your-password>"
        document_id => "%{id}"
        cacert => "/tmp/ca.crt"
    }
}
Two details do most of the work here. schedule is standard cron syntax—* * * * * runs every minute; in the lab I also ran the hourly variant 0 * * * *. And document_id => "%{id}" maps the primary key to the Elasticsearch _id, which is what makes repeated runs idempotent. The stdout output is your friend during development; remove it in production. Full option reference lives in the Logstash JDBC input docs.
Incremental sync: three real scenarios
Pulling SELECT * FROM table every minute works for small tables. Beyond that, you need a strategy. These are the three patterns from the lab notes.
Scenario 1: append-only table with an id
Rows are only inserted, never updated. Track the highest id you have seen with sql_last_value:
input {
  jdbc {
    statement => "SELECT id, col1, col2 FROM my_table WHERE id > :sql_last_value"
    use_column_value => true
    tracking_column => "id"
    # ... connection settings
  }
}
Each scheduled run, Logstash substitutes the persisted sql_last_value (stored in the .logstash_jdbc_last_run file) and fetches only new rows. A timestamp-type tracking_column on an updated_at column extends this to catch updates too—as long as your application reliably maintains that column.
Scenario 2: rows get updated
Pull everything each run, but pin the document id:
output {
    elasticsearch {
        document_id => "%{id}"
        # ... other settings
    }
}
Because the _id is stable, re-indexed rows overwrite the old document instead of duplicating it. Simple, correct, and fine until table size makes full re-pulls expensive.
Scenario 3: no primary key
Combine columns into a synthetic id: document_id => "%{col1}-%{col2}". Make sure the combination is genuinely unique, or you will silently merge rows.
The honest part: deletes
The JDBC input runs SQL queries. A deleted row simply stops appearing in results—Logstash never learns it existed, so the stale document stays in Elasticsearch forever. Options, in increasing order of effort:
- Soft deletes: add a
deletedflag column instead of deleting rows, sync it, and filter it out at query time (or use it to drive a delete action in the output). - Periodic rebuild: reindex into a fresh index on a schedule and swap an alias—stale documents disappear on each swap.
- Real CDC: if deletes must propagate in near real time, move to change-data-capture (Debezium + Kafka reading the Postgres WAL). More infrastructure, but it sees every insert, update, and delete.
If deletes are rare and tolerable for a day, alias-swap rebuilds are the pragmatic answer. Do not pretend the JDBC input handles this—it does not.
Verifying the data in Elasticsearch
Once the country and city indices fill up, the payoff is query flexibility Postgres cannot match without extensions:
GET city/_search
{
  "query": {
    "bool": {
      "must": [
        { "match": { "name.keyword": "Cambridge" } },
        { "range": { "population": { "gte": 110000 } } }
      ]
    }
  }
}
Terms aggregations on name.keyword, wildcard queries like Cam*, and everything else in Query DSL now run against your relational data. Kibana Dev Tools (port 5601) is the fastest console for this. Once the pipeline is live, watch indexing rate and rejections like any other ingest path—that is precisely what we cover in Elasticsearch monitoring.
No throughput or latency benchmarks in this guide: the source lab did not measure them, and I do not invent numbers.
Frequently Asked Questions
How often should the Logstash JDBC input run?
schedule accepts cron syntax, so anything from every minute (* * * * *) to hourly (0 * * * *) or nightly. Match it to how fresh search results must be and how much load your database tolerates. For sub-second freshness, JDBC polling is the wrong tool—look at CDC.
Does the JDBC input handle deleted rows?
No. A SQL poll cannot see rows that no longer exist. Use soft-delete flags, scheduled full reindexes behind an alias, or a CDC pipeline (Debezium/Kafka) if deletes must reach Elasticsearch.
Why are my documents duplicated on every run?
You have not set document_id. Without it, Elasticsearch auto-generates an _id per bulk request, so every scheduled run inserts fresh copies. Map your primary key with document_id => "%{id}".
Where does Logstash store sql_last_value?
In a metadata file (by default .logstash_jdbc_last_run in the Logstash user's home, configurable via last_run_metadata_path). Delete that file to force a full re-sync from the beginning.
Key Takeaways
- One jar, one config file is genuinely all it takes to get Postgres data searchable—copy the JDBC driver into Logstash and write a
jdbcinput. - Always set
document_idfrom your primary key. It is the difference between idempotent syncs and an index full of duplicates. - Use
sql_last_value+tracking_columnfor append-only or timestamp-tracked tables instead of re-pulling the whole table every minute. - Deletes never propagate through JDBC polling—decide upfront between soft deletes, alias-swap rebuilds, or CDC.
- Keep
stdout {}in the output while developing, drop it in production. - TLS is not optional in modern Elasticsearch—copy the cluster CA (
ca.crt) out of the container and reference it withcacertin the output.
Running this pattern at real scale, or unsure whether JDBC polling or CDC fits your case? Reach out at searchali.com.